
The problem at hand
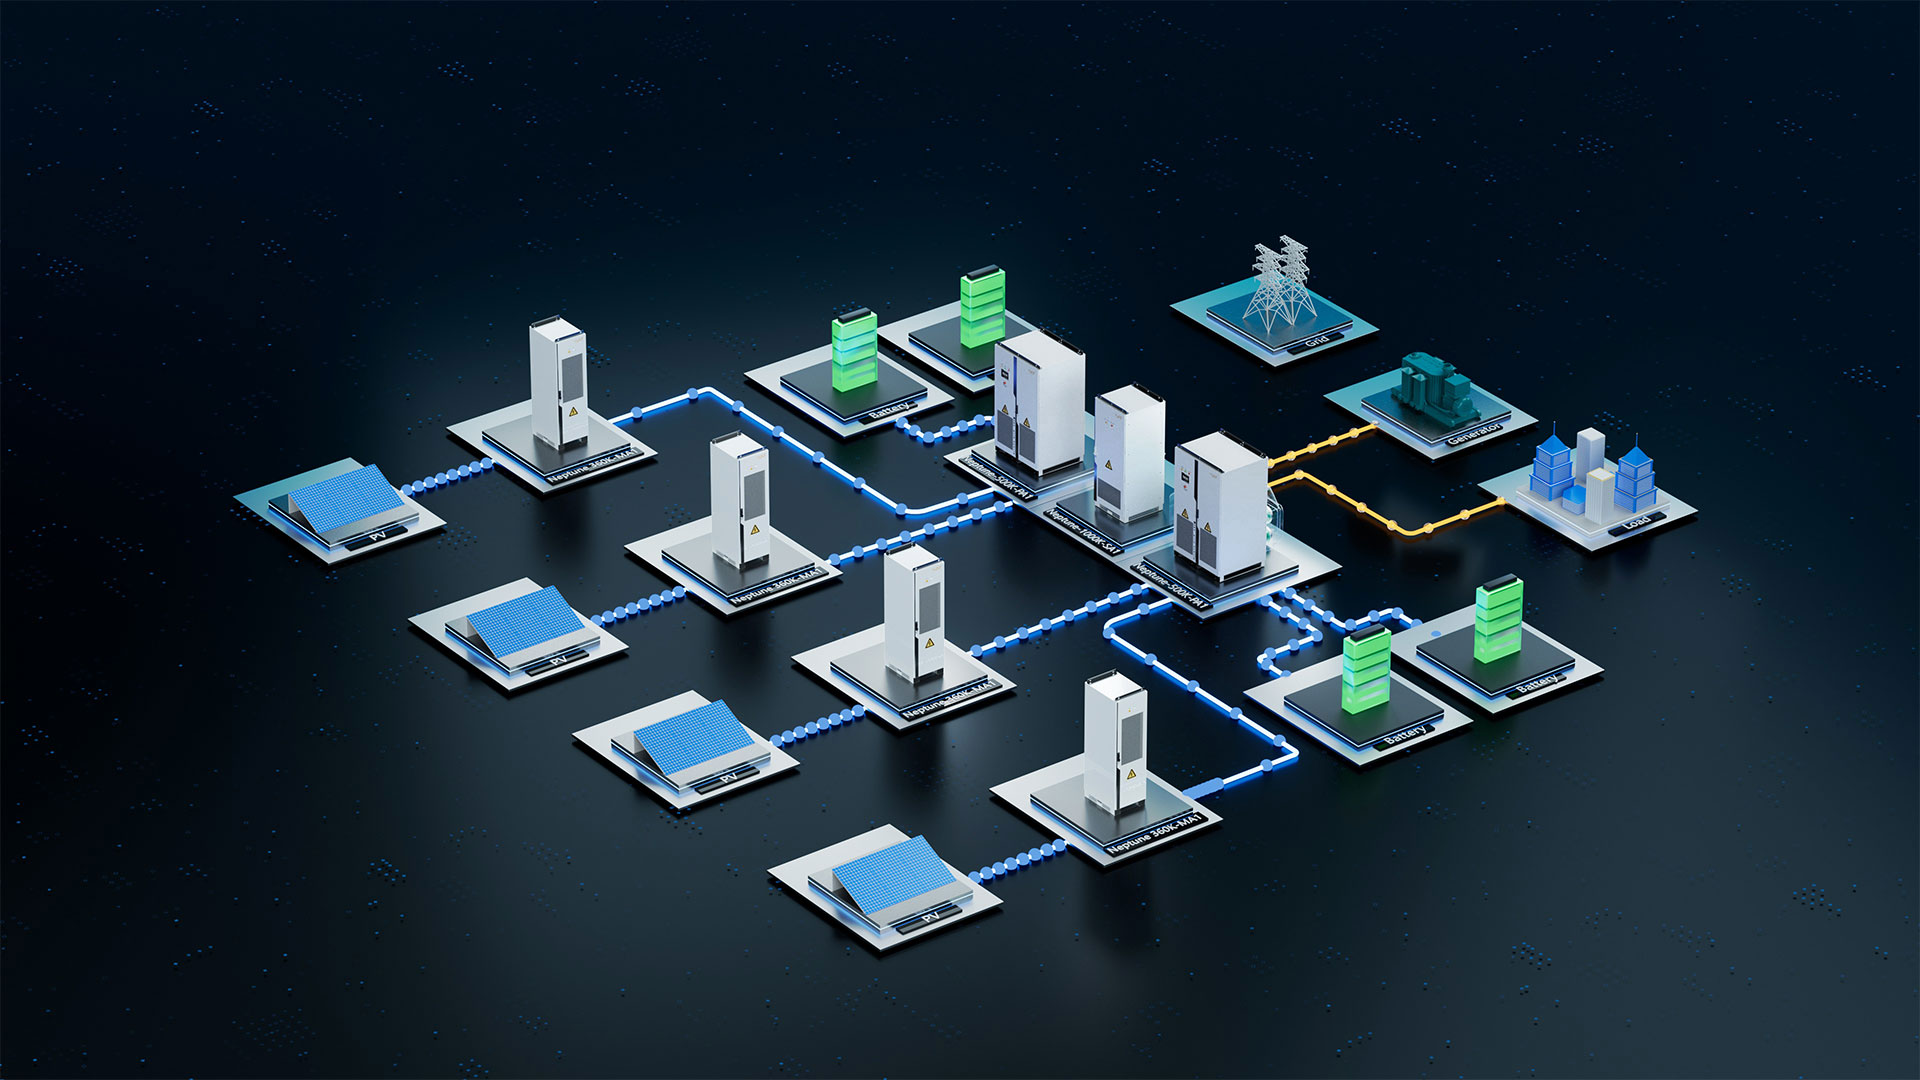
Microgrid teams are up against a narrow technical window: BMS-to-EMS Modbus TCP register polling latency can make or break bulk energy storage behaviour when rapid switching and state updates are required. On a Cape Town rooftop or a community microgrid coping with recurring load-shedding, slow or jittery polling turns control intent into delayed reality. Early in the design phase, include considerations for physical switching hardware—like static transfer switches—because the mechanical and control interfaces must match the latency budget the software promises.
Why latency becomes a system-level constraint
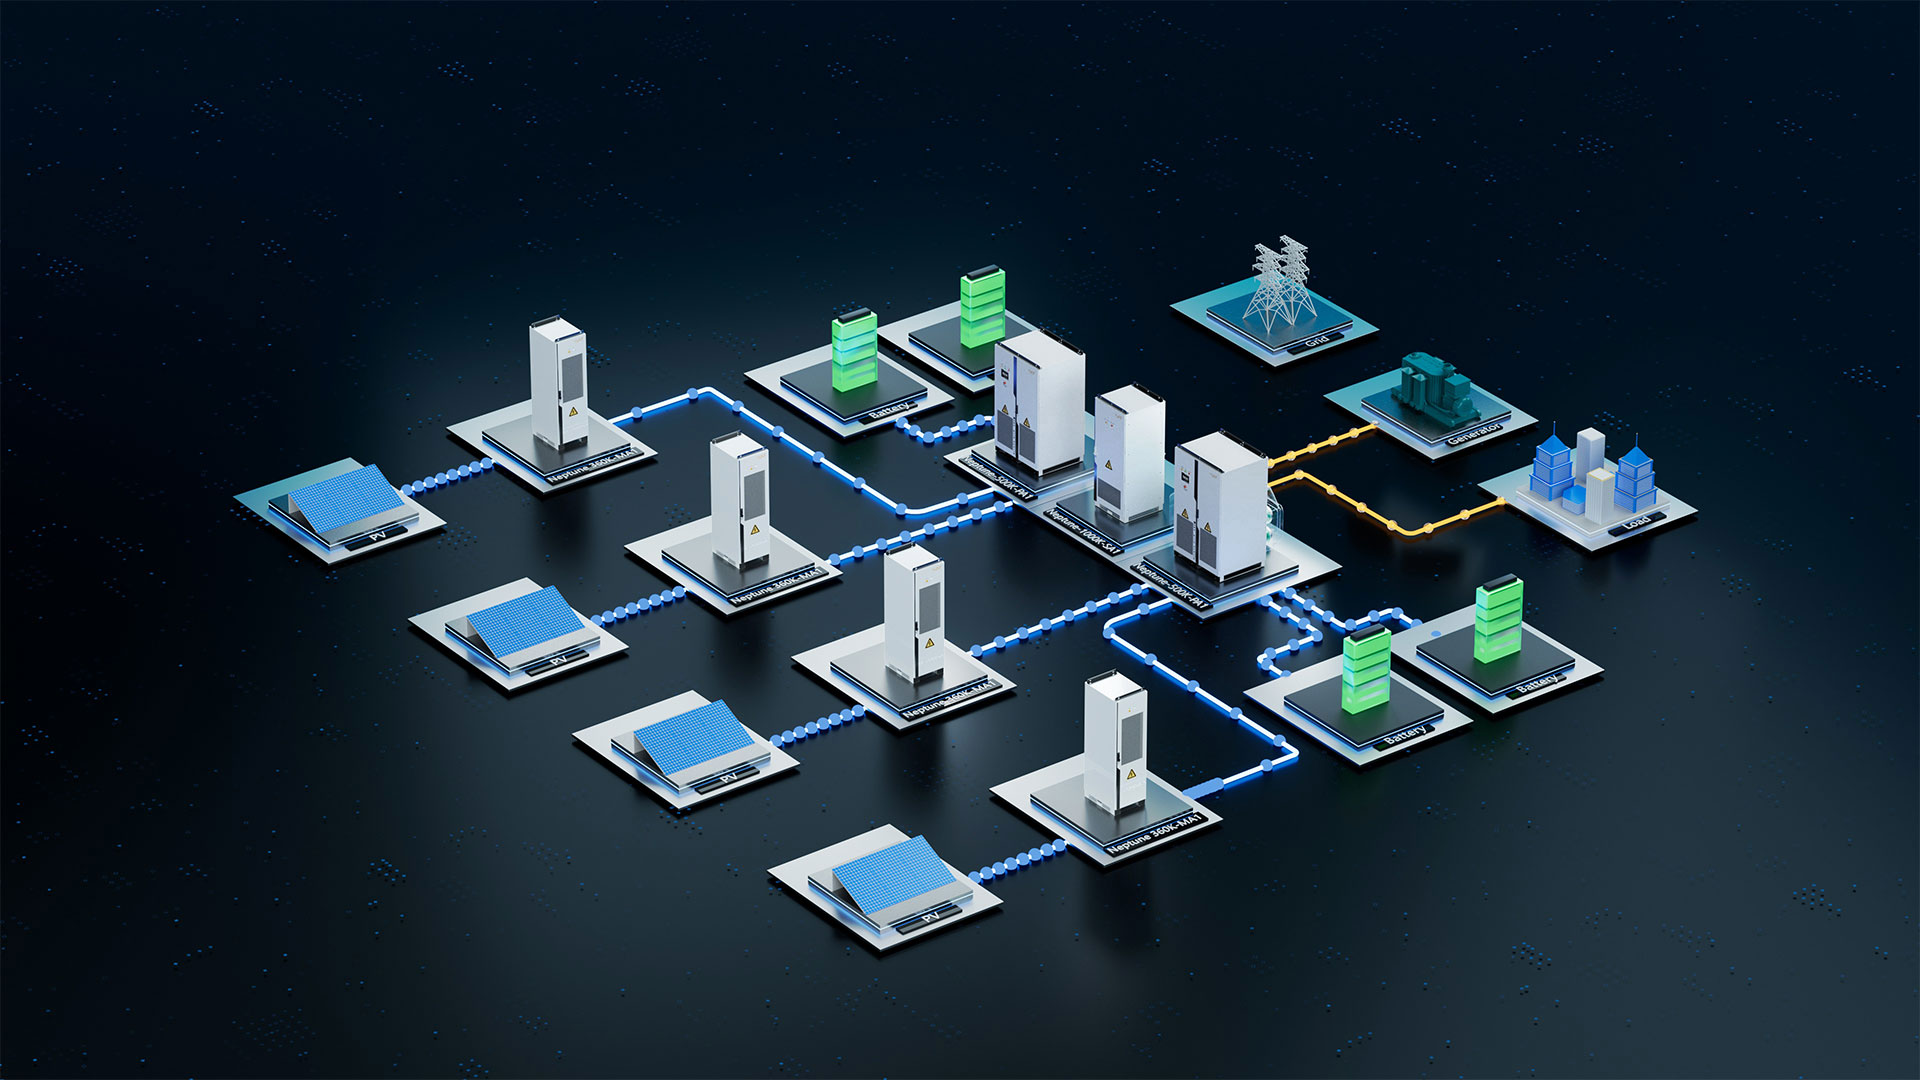
Modbus TCP is simple and widely used, but it wasn’t designed for ultra-low deterministic timing. Register polling latency stacks: network hops, TCP retransmits, BMS processing, EMS scheduling. That stack affects SOC reporting, cell balancing commands and protection trip timing. For bulk ESS the penalty is tangible—slower state-of-charge convergence, delayed safety triggers, and mismatched setpoints for inverters and static transfer switch actions. Even SCADA dashboards start to lie about what’s happening right now.
Engineering trade-offs and hard limits
Designers must treat polling latency as an engineering parameter, not a nuisance. Lower poll intervals mean higher packet rates and CPU load on BMS/EMS devices; higher intervals reduce control fidelity. Typical constraints include TCP window sizes, Modbus register map simplicity, and deterministic CPU scheduling inside the EMS. Where you need sub-200 ms closed-loop responsiveness, you often must move from uncoordinated polling to event-driven telemetry or local interlocks at the static transfer switch level. Use terms like BMS, EMS and Modbus TCP when mapping these constraints into your BOM and test plans.
Practical mitigations and architecture choices
Start by mapping the critical registers. Prioritise protection and real-time state registers; non-urgent telemetry can live on slower cycles. Reduce register size and align reads to contiguous blocks to avoid multiple Modbus function calls. Consider UDP-based telemetry for non-critical streams, or introduce a local gateway that aggregates and timestamps data before forwarding to the EMS. For deterministic switching, hard interlocks on the static transfer switch manufacturers’ hardware are worth their weight—let the switch act first, report later.
Common mistakes and reasonable alternatives
Teams often assume network latency is the only variable; they forget device CPU and register mapping. Expect software jitter: garbage collection pauses, logging bursts, or SNMP traps can push a poll cycle out by tens to hundreds of milliseconds. – A wiser path is to test under load with realistic traffic and inject faults early. Alternatives include pushing intelligence to edge controllers, using time-synchronised telemetry or implementing a lightweight binary protocol between BMS and EMS that respects the timing budget but preserves reliability.
Field anchor and practitioner perspective
EEAT: practitioner perspective — from commissioning in South African municipal sites during the 2020–2023 load-shedding escalation, we measured Modbus TCP round-trip variation of 30–450 ms across different LANs. That real-world anchor shows why planners must budget worst-case latency, not averages. When a microgrid must flip sources quickly, the static transfer switch and the BMS must agree on intent within the same timeframe; otherwise, you get race conditions and unnecessary trips.
Golden rules for selection and validation
Three critical evaluation metrics to use before committing hardware or firmware: 1) determinism: measure 95th-percentile round-trip time for your register set under full load; design to that bound. 2) atomicity: ensure crucial setpoints and trip commands are read/written in single Modbus operations where possible, to avoid partial updates. 3) fail-safe behaviour: validate local interlocks on the static transfer switch and BMS so control actions occur even if the EMS loses contact. Track {main_keyword} and {variation_keyword} during bench tests and in-field trials to prove compliance.
The value here lands in clear trade-offs and tested thresholds; designers who set latency budgets and defend them via hardware choices save hours of rework. For teams wanting a practical, tested approach that ties switching hardware to control logic, YUNT sits naturally in the stack as the partner that aligns static transfer switch behaviour with your EMS and BMS timelines—making system-level reliability a practical reality. –